Larry Wasserman has started the Normal Deviate blog which I added to the blogroll on the right.
Manfred Warmuth points out the UCSC machine learning summer school running July 9-20 which may be of particular interest to those in silicon valley.
Machine learning and learning theory research
Larry Wasserman has started the Normal Deviate blog which I added to the blogroll on the right.
Manfred Warmuth points out the UCSC machine learning summer school running July 9-20 which may be of particular interest to those in silicon valley.
People are naturally interested in slicing the ICML acceptance statistics in various ways. Here’s a rundown for the top categories.
| 18/66 = 0.27 | in (0.18,0.36) | Reinforcement Learning |
| 10/52 = 0.19 | in (0.17,0.37) | Supervised Learning |
| 9/51 = 0.18 | not in (0.18, 0.37) | Clustering |
| 12/46 = 0.26 | in (0.17, 0.37) | Kernel Methods |
| 11/40 = 0.28 | in (0.15, 0.4) | Optimization Algorithms |
| 8/33 = 0.24 | in (0.15, 0.39) | Learning Theory |
| 14/33 = 0.42 | not in (0.15, 0.39) | Graphical Models |
| 10/32 = 0.31 | in (0.15, 0.41) | Applications (+5 invited) |
| 8/29 = 0.28 | in (0.14, 0.41]) | Probabilistic Models |
| 13/29 = 0.45 | not in (0.14, 0.41) | NN & Deep Learning |
| 8/26 = 0.31 | in (0.12, 0.42) | Transfer and Multi-Task Learning |
| 13/25 = 0.52 | not in (0.12, 0.44) | Online Learning |
| 5/25 = 0.20 | in (0.12, 0.44) | Active Learning |
| 6/22 = 0.27 | in (0.14, 0.41) | Semi-Supervised Learning |
| 7/20 = 0.35 | in (0.1, 0.45) | Statistical Methods |
| 4/20 = 0.20 | in (0.1, 0.45) | Sparsity and Compressed Sensing |
| 1/19 = 0.05 | not in (0.11, 0.42) | Ensemble Methods |
| 5/18 = 0.28 | in (0.11, 0.44) | Structured Output Prediction |
| 4/18 = 0.22 | in (0.11, 0.44) | Recommendation and Matrix Factorization |
| 7/18 = 0.39 | in (0.11, 0.44) | Latent-Variable Models and Topic Models |
| 1/17 = 0.06 | not in (0.12, 0.47) | Graph-Based Learning Methods |
| 5/16 = 0.31 | in (0.13, 0.44) | Nonparametric Bayesian Inference |
| 3/15 = 0.20 | in (0.7, 0.47) | Unsupervised Learning and Outlier Detection |
| 7/12 = 0.58 | not in (0.08, 0.50) | Gaussian Processes |
| 5/11 = 0.45 | not in (0.09, 0.45) | Ranking and Preference Learning |
| 2/11 = 0.18 | in (0.09, 0.45) | Large-Scale Learning |
| 0/9 = 0.00 | in [0, 0.56) | Vision |
| 3/9 = 0.33 | in [0, 0.56) | Social Network Analysis |
| 0/9 = 0.00 | in [0, 0.56) | Multi-agent & Cooperative Learning |
| 2/9 = 0.22 | in [0, 0.56) | Manifold Learning |
| 4/8 = 0.50 | not in [0, 0.5) | Time-Series Analysis |
| 2/8 = 0.25 | in [0, 0.5] | Large-Margin Methods |
| 2/8 = 0.25 | in [0, 0.5] | Cost Sensitive Learning |
| 2/7 = 0.29 | in [0, 0.57) | Recommender Systems |
| 3/7 = 0.43 | in [0, 0.57) | Privacy, Anonymity, and Security |
| 0/7 = 0.00 | in [0, 0.57) | Neural Networks |
| 0/7 = 0.00 | in [0, 0.57) | Empirical Insights |
| 0/7 = 0.00 | in [0, 0.57) | Bioinformatics |
| 1/6 = 0.17 | in [0, 0.5) | Information Retrieval |
| 2/6 = 0.33 | in [0, 0.5) | Evaluation Methodology |
Update: See Brendan’s graph for a visualization.
I usually find these numbers hard to interpret. At the grossest level, all areas have significant selection. At a finer level, one way to add further interpretation is to pretend that the acceptance rate of all papers is 0.27, then compute a 5% lower tail and a 5% upper tail. With 40 categories, we expect to have about 4 violations of tail inequalities. Instead, we have 9, so there is some evidence that individual areas are particularly hot or cold. In particular, the hot topics are Graphical models, Neural Networks and Deep Learning, Online Learning, Gaussian Processes, Ranking and Preference Learning, and Time Series Analysis. The cold topics are Clustering, Ensemble Methods, and Graph-Based Learning Methods.
We also experimented with AIStats resubmits (3/4 accepted) and NFP papers (4/7 accepted) but the numbers were to small to read anything significant.
One thing that surprised me was how uniform decisions were as a function of average score in reviews. All reviews included a decision from {Strong Reject, Weak Reject, Weak Accept, Strong Accept}. These were mapped to numbers in the range {1,2,3,4}. In essence, average review score < 2.2 meant 0% chance of acceptance, and average review score > 3.1 meant acceptance. Due to discretization in the number of reviewers and review scores there were only 3 typical uncertain outcomes:
One question I’ve always wondered is: How much variance is there in the accept/reject decision? In general, correlated assignment of reviewers can greatly increase the amount of variance, so one of our goals this year was doing as independent an assignment as possible. If you accept that as independence, we essentially get 3 samples for each paper where the average standard deviation of reviewer scores before author feedback and discussion is 0.64. After author feedback and discussion the standard deviation drops to 0.51. If we pretend that papers have an intrinsic value between 1 and 4 then think of reviews as discretized gaussian measurements fed through the above decision criteria, we get the following:
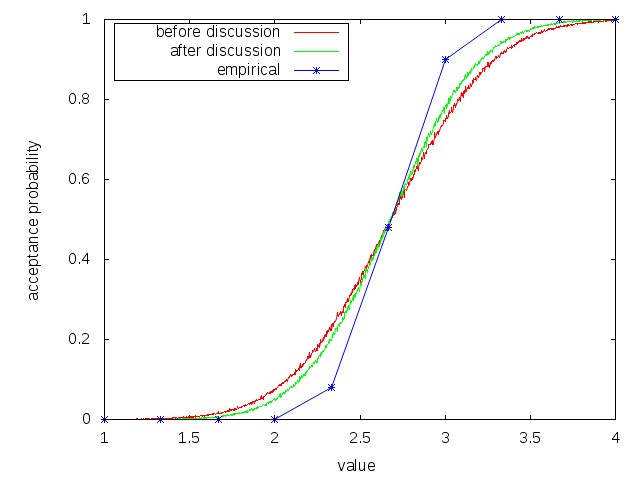
There are great caveats to this picture. For example, treating the AC’s decision as random conditioned on the reviewer average is a worst-case analysis. The reality is that ACs are removing noise from the few events that I monitored carefully, although it is difficult to quantify this. Similarly, treating the reviews observed after discussion as independent is clearly flawed. A reasonable way to look at it is: author feedback and discussion get us about 1/3 or 1/4 of the way to the final decision from the initial reviews.
Conditioned on the papers, discussion, author feedback and reviews, AC’s are pretty uniform in their decisions with ~30 papers where ACs disagreed on the accept/reject decision. For half of those, the ACs discussed further and agreed, leaving Joelle and I a feasible quantity of cases to look at (plus several other exceptions).
At the outset, we promised a zero-spof reviewing process. We actually aimed higher: at least 3 people needed to make a wrong decision for the ICML 2012 reviewing process to kick out a wrong decision. I expect this happened a few times given the overall level of quality disagreement and quantities involved, but hopefully we managed to reduce the noise appreciably.
The accepted papers are up in full detail. We are still struggling with the precise program itself, but that’s coming along. Also note the May 13 deadline for early registration and room booking.
Yahoo! laid off people. Unlike every previous time there have been layoffs, this is serious for Yahoo! Research.
We had advanced warning from Prabhakar through the simple act of leaving. Yahoo! Research was a world class organization that Prabhakar recruited much of personally, so it is deeply implausible that he would spontaneously decide to leave. My first thought when I saw the news was “Uhoh, Rob said that he knew it was serious when the head of ATnT Research left.” In this case it was even more significant, because Prabhakar recruited me on the premise that Y!R was an experiment in how research should be done: via a combination of high quality people and high engagement with the company. Prabhakar’s departure is a clear end to that experiment.
The result is ambiguous from a business perspective. Y!R clearly was not capable of saving the company from its illnesses. I’m not privy to the internal accounting of impact and this is the kind of subject where there can easily be great disagreement. Even so, there were several strong direct impacts coming from the machine learning, economics, and algorithms groups.
Y!R clearly was excellent from an academic research perspective. On a per person basis in relevant subjects, it was outstanding. One way to measure this is by noticing that both ICML and KDD had (co)program chairs from Y!R. It turns out that talking to the rest of the organization doing consulting, architecting, and prototyping on a minority basis helps research by sharpening the questions you ask more than it hinders by taking up time. The decision to participate in this experiment was a good one for me personally.
It has been clear in silicon valley, academia, and pretty much everywhere else that people at Yahoo! including Yahoo! Research have been looking around for new positions. Maintaining the excellence of Y!R in a company that has been under prolonged stress was challenging leadership-wise. Consequently, the abrupt departure of Prabhakar and an apparent lack of appreciation by the new CEO created a crisis of confidence. Many people who were sitting on strong offers quickly left, and everyone else started looking around.
In this situation, my first concern was for colleagues, both in Machine Learning across the company and the Yahoo! Research New York office.
Machine Learning turns out to be a very hot technology. Every company and government in the world is drowning in data, and Machine Learning is the prime tool for actually using it to do interesting things. More generally, the demand for high quality seasoned machine learning researchers across startups, mature companies, government labs, and academia has been astonishing, and I expect the outcome to reflect that. This is remarkably different from the cuts that hit ATnT research in late 2001 and early 2002 where the famous machine learning group there took many months to disperse to new positions.
In the New York office, we investigated many possibilities hard enough that it became a news story. While that article is wrong in specifics (we ended up not fired for example, although it is difficult to discern cause and effect), we certainly shook the job tree very hard to see what would fall out. To my surprise, amongst all the companies we investigated, Microsoft had a uniquely sufficient agility, breadth of interest, and technical culture, enabling them to make offers that I and a significant fraction of the Y!R-NY lab could not resist. My belief is that the new Microsoft Research New York City lab will become an even greater techhouse than Y!R-NY. At a personal level, it is deeply flattering that they have chosen to create a lab for us on short notice. I will certainly do my part chasing the greatest learning algorithms not yet invented.
In light of this, I would encourage people in academia to consider Yahoo! in as fair a light as possible in the current circumstances. There are and will be some serious hard feelings about the outcome as various top researchers elsewhere in the organization feel compelled to look for jobs and leave. However, Yahoo! took a real gamble supporting a research organization about 7 years ago, and many positive things have come of this gamble from all perspectives. I expect almost all of the people leaving to eventually do quite well, and often even better.
What about ICML? My second thought on hearing about Prabhakar’s departure was “I really need to finish up initial paper/reviewer assignments today before dealing with this”. During the reviewing period where the program chair load is relatively light, Joelle handled nearly everything. My great distraction ended neatly in time to help with decisions at ICML. I considered all possibilities in accepting the job and was prepared to simply put aside a job search for some time if necessary, but the timing was surreally perfect. All signs so far point towards this ICML being an exceptional ICML, and I plan to do everything that I can to make that happen. The early registration deadline is May 13.
What about KDD? Deepak was sitting on an offer at Linkedin and simply took it, so the disruption there was even more minimal. Linkedin is a significant surprise winner in this affair.
What about Vowpal Wabbit? Amongst other things, VW is the ultrascale learning algorithm, not the kind of thing that you would want to put aside lightly. I negotiated to continue the project and succeeded. This surprised me greatly—Microsoft has made serious commitments to supporting open source in various ways and that commitment is what sealed the deal for me. In return, I would like to see Microsoft always at or beyond the cutting edge in machine learning technology.
added: crosspost on CACM.
added: Lance, Jennifer, NYTimes, Vader
May 16 in Cambridge, is the New England Machine Learning Day, a first regional workshop/symposium on machine learning. To present a poster, submit an abstract by May 5.
May 19 in New York, STOC is coming to town and rather surprisingly having workshops which should be quite a bit of fun. I’ll be speaking at Algorithms for Distributed and Streaming Data.