Online learning or online preservation of learning?

In the online learning with experts setting, you observe a set of predictions, make a decision, and then observe the truth. This process repeats indefinitely. In this setting, it is possible to prove theorems of the sort:

master algorithm error count < = k* best predictor error count + c*log(number of predictors)

Is this a statement about learning or about preservation of learning? We did some experiments to analyze the new Binning algorithm which works in this setting. For several UCI datasets, we reprocessed them so that features could be used as predictors and then applied several master algorithms. The first graph confirms that Binning is indeed a better algorithm according to the tightness of the upper bound.
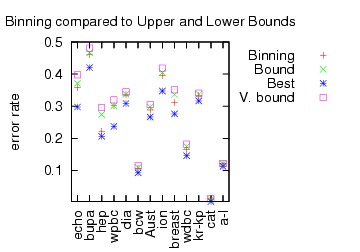

Here, “Best” is the performance of the best expert. “V. Bound” is the bound for Vovk‘s algorithm (the previous best). “Bound” is the bound for the Binning algorithm. “Binning” is the performance of the Binning algorithm. The Binning algorithm clearly has a tighter bound, and the performance bound is clearly a sharp constraint on the algorithm performance.

Instead of examining bounds, we can simply look at performance.
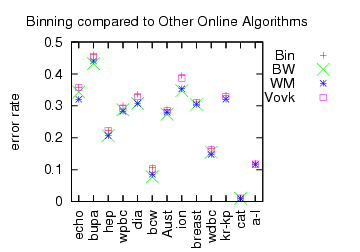

“Bin” is the performance of Binning (identical to the previous graph). BW is Binomial weighting, which is (roughly) the deterministic version of Binning. WM is Weighted Majority. Both BW and WM are deterministic algorithms which implies their performance bounds are perhaps a factor of 2 worse than Binning or Vovk’s algorithm.

In contrast, the actual performance (rather than performance bound) of the deterministic algorithms is sometimes even better than the best expert (negative regret?!). A consistent negative correlation between “online bound tightness” and “learning performance” is observed.

The question is “What’s happening here?”

  1. One reply is that we are testing in the wrong setting. These algorithms are designed to work in highly adversarial environments for which a UCI dataset does not qualify. This isn’t a convincing answer to me because many (or perhaps most) situations are not that adversarial.
  2. Another answer is “you used the wrong experts”. This is not convincing because many other learning algorithm do as well or better with the given features/experts.
  3. Another possibility is “you can start out running Binning, and when it pulls ahead of it’s bound run any learning algorithm. If the learning algorithm does badly, you can switch back to Binning and preserve the guarantee.” So, Binning is effectively a safety net.

My best current understanding is that “online learning with experts” is really “online preservation of learning”: the goal of the algorithm is to preserve whatever predictive ability the individual predictors have. This understanding fits the form of the theory statement well.

Preservation is desirable in some situations. For example, charity events sometimes work according to the following form:

  1. All participants exchange dollars for bogobucks.
  2. The participants gamble with bogobucks.
  3. The winner at the end gets some prize.

An online preservation algorithm has the property that if you acquire enough bogobucks in comparison to the number of participants, you can guarantee winning the prize. These kinds of ‘winner take all’ scenarios come up elsewhere.

“Structural” Learning

Fernando Pereira pointed out Ando and Zhang‘s paper on “structural” learning. Structural learning is multitask learning on subproblems created from unlabeled data.

The basic idea is to take a look at the unlabeled data and create many supervised problems. On text data, which they test on, these subproblems might be of the form “Given surrounding words predict the middle word”. The hope here is that successfully predicting on these subproblems is relevant to the prediction of your core problem.

In the long run, the precise mechanism used (essentially, linear predictors with parameters tied by a common matrix) and the precise problems formed may not be critical. What seems critical is that the hope is realized: the technique provides a significant edge in practice.

Some basic questions about this approach are:

  1. Are there effective automated mechanisms for creating the subproblems?
  2. Is it necessary to use a shared representation?

Why do people count for learning?

This post is about a confusion of mine with respect to many commonly used machine learning algorithms.

A simple example where this comes up is Bayes net prediction. A Bayes net where a directed acyclic graph over a set of nodes where each node is associated with a variable and the edges indicate dependence. The joint probability distribution over the variables is given by a set of conditional probabilities. For example, a very simple Bayes net might express:
P(A,B,C) = P(A | B,C)P(B)P(C)

What I don’t understand is the mechanism commonly used to estimate P(A | B, C). If we let N(A,B,C) be the number of instances of A,B,C then people sometimes form an estimate according to:

P'(A | B,C) = N(A,B,C) / N /[N(B)/N * N(C)/N] = N(A,B,C) N /[N(B) N(C)]

… in other words, people just estimate P'(A | B,C) according to observed relative frequencies. This is a reasonable technique when you have a large number of samples compared to the size space A x B x C, but it (naturally) falls apart when this is not the case as typically happens with “big” learning problems such as machine translation, vision, etc…

To compensate, people often try to pick some prior (such as Dirichlet prior with one “virtual count” per joint parameter setting) to provide a reasonable default value for the count. Naturally, in the “big learning” situations where this applies, the precise choice of prior can greatly effect the system performance leading to finicky tuning of various sorts. It’s also fairly common to fit some parametric model (such as a Gaussian) in an attempt to predict A given B and C.

Stepping back a bit, we can think of the estimation of P(A | B, C) as a simple self-contained prediction (sub)problem. Why don’t we use existing technology for doing this prediction? Viewed as a learning algorithm “counting with a Dirichlet prior” is exactly memorizing the training set and then predicting according to either (precisely) matching training set elements or using a default. It’s hard to imagine a more primitive learning algorithm.

There seems to be little downside to trying this approach. In low count situations, a general purpose prediction algorithm has a reasonable hope of performing well. In a high count situation, any reasonable general purpose algorithm converges to the same estimate as above. In either case something reasonable happens.

Using a general purpose probabilistic prediction algorithm isn’t a new idea, (for example, see page 57), but it appears greatly underutilized. This is a very small modification of existing systems with a real hope of dealing with low counts in {speech recognition, machine translation, vision}. It seems that using a general purpose probabilistic prediction algorithm should be the default rather than the exception.

The Peekaboom Dataset

Luis von Ahn‘s Peekaboom project has yielded data (830MB).

Peekaboom is the second attempt (after Espgame) to produce a dataset which is useful for learning to solve vision problems based on voluntary game play. As a second attempt, it is meant to address all of the shortcomings of the first attempt. In particular:

  1. The locations of specific objects are provided by the data.
  2. The data collection is far more complete and extensive.

The data consists of:

  1. The source images. (1 file per image, just short of 60K images.)
  2. The in-game events. (1 file per image, in a lispy syntax.)
  3. A description of the event language.

There is a great deal of very specific and relevant data here so the hope that this will help solve vision problems seems quite reasonable.

A Fundamentalist Organization of Machine Learning

There are several different flavors of Machine Learning classes. Many classes are of the ‘zoo’ sort: many different learning algorithms are presented. Others avoid the zoo by not covering the full scope of machine learning.

This is my view of what makes a good machine learning class, along with why. I’d like to specifically invite comment on whether things are missing, misemphasized, or misplaced.

Phase Subject Why?
Introduction What is a machine learning problem? A good understanding of the characteristics of machine learning problems seems essential. Characteristics include: a data source, some hope the data is predictive, and a need for generalization. This is probably best taught in a case study manner: lay out the specifics of some problem and then ask “Is this a machine learning problem?”
Introduction Machine Learning Problem Identification Identification and recognition of the type of learning problems is (obviously) a very important step in solving such problems. People need to be familiar witth the concept of ‘regression’, ‘classification’, ‘cost sensitive classification’, ‘reinforcement learning’, etc… A good organization of these things is possible, but not yet well done.
Introduction Example algorithm 1 To really understand machine learning, a couple learning algorithms must be understood in detail.
Introduction Example algorithm 2 Ditto. The reason why the number is “2” and not “1” or “3” is that 2 is the minimum number required to make people naturally aware of the degrees of freedom available in learning algorithm design.
Analysis Bias for Learning The need for a good bias is one of the defining characteristics of learning. This includes discussing the means to specify bias (via Bayesian priors, choice of features, graphical models, etc…). This statement is generic so it will always apply to one degree or another.
Analysis Learning can be boosted. This is the boosting observation: that it is possible to bootstrap predictive ability to create a better overall system. This statement is similarly generic.
Analysis Learning can be transformed This is the reductions observation: that the ability to solve one kind of learning problems implies the ability to solve other kinds of leanring problems. This statement is similarly generic.
Analysis Learning can be preserved This is the online learning with experts observation: that we can have a master algorithm which preserves the best learning performance of subalgorithms. This statement is again generic.
Analysis Overfitting Learning algorithms can easily overfit to existing training data. How to analyze this (with an IID assumption), and how to avoid it are very important for success.
Analysis Hardness of Learning It turns out that there are several different ways in which machine learning can be hard including computational and information theoretic hardness. Some of PAC learning is relevant here. An understanding of how and why learning algorithms can fail seems important to understand the process.
Applications Vision One example of how learning is applied to solve vision problems.
Applications Language Ditto for language problems.
Applications Robotics Ditto for robotics
Applications Speech Ditto for speech
Applications Businesses Ditto for businesses
Where is machine learning going? Insert predictions of the future here. It should be understood that the field of machine learning is changing rapidly.

The emphasis here is on fundamentals: generally applicable mathematical statements and understandings of the learning problem. Given that emphasis, the ‘applications’ section could be cut without harming the integrity of the purpose.