Interesting papers at ICML 2014

This year’s ICML had several papers which I want to read through more carefully and understand better.

  1. Chun-Liang Li, Hsuan-Tien Lin, Condensed Filter Tree for Cost-Sensitive Multi-Label Classification. Several tricks accumulate to give a new approach for addressing cost sensitive multilabel classification.
  2. Nikos Karampatziakis and Paul Mineiro, Discriminative Features via Generalized Eigenvectors. An efficient, effective eigenvalue solution for supervised learning yields compelling nonlinear performance on several datasets.
  3. Nir Ailon, Zohar Karnin, Thorsten Joachims, Reducing Dueling Bandits to Cardinal Bandits. An effective method for reducing dueling bandits to normal bandits that extends to contextual situations.
  4. Pedro Pinheiro, Ronan Collobert, Recurrent Convolutional Neural Networks for Scene Labeling. Image parsing remains a challenge, and this is plausibly a step forward.
  5. Cicero Dos Santos, Bianca Zadrozny, Learning Character-level Representations for Part-of-Speech Tagging. Word morphology is clearly useful information, and yet almost all ML-for-NLP applications ignore it or hard-code it (by stemming).
  6. Alekh Agarwal, Daniel Hsu, Satyen Kale, John Langford, Lihong Li, Robert Schapire, Taming the Monster: A Fast and Simple Algorithm for Contextual Bandits. Statistically efficient interactive learning is now computationally feasible. I wish this one had been done in time for the NIPS tutorial 🙂
  7. David Silver, Guy Lever, Nicolas Heess, Thomas Degris, Daan Wierstra, Martin Riedmiller, Deterministic Policy Gradient Algorithms. A reduction in variance from working out the deterministic limit of policy gradient make policy gradient approaches look much more attractive.

Edit: added one that I forgot.
An ICML proposal: yearly surveys

I’d like to propose that ICML conducts a yearly survey similar to the one from 2010 or 2012 which is reported to all.

The key reason for this is information: I expect everyone participating in ICML has some baseline interest in how ICML is doing. Everyone involved has personal anecdotal information, but we all understand that a few examples can be highly misleading.

Aside from satisfying everyone’s joint curiousity, I believe this could improve ICML itself. Consider for example reviewing. Every program chair comes in with ideas for how to make reviewing better. Some succeed, but nearly all are forgotten by the next round of program chairs. Making survey information available will help quantify success and correlate it with design decisions.

The key question to ask for this is “who?” The reason why surveys don’t happen more often is that it has been the responsibility of program chairs who are typically badly overloaded. I believe we should address this by shifting the responsibility to a multiyear position, similar to or the same as a webmaster. This may imply a small cost to the community (<$1/participant) for someone's time to do and record the survey, but I believe it's a worthwhile cost. I plan to bring this up with IMLS board in Beijing, but would like to invite any comments or thoughts.

The New York ML Symposium, take 2

The 201314 is New York Machine Learning Symposium is finally happening on March 28th at the New York Academy of Science. Every invited speaker interests me personally. They are:

We’ve been somewhat disorganized in advertising this. As a consequence, anyone who has not submitted an abstract but would like to do so may send one directly to me (jl@hunch.net title NYASMLS) by Friday March 14. I will forward them to the rest of the committee for consideration.

NIPS tutorials and Vowpal Wabbit 7.4

At NIPS I’m giving a tutorial on Learning to Interact. In essence this is about dealing with causality in a contextual bandit framework. Relative to previous tutorials, I’ll be covering several new results that changed my understanding of the nature of the problem. Note that Judea Pearl and Elias Bareinboim have a tutorial on causality. This might appear similar, but is quite different in practice. Pearl and Bareinboim’s tutorial will be about the general concepts while mine will be about total mastery of the simplest nontrivial case, including code. Luckily, they have the right order. I recommend going to both 🙂

I also just released version 7.4 of Vowpal Wabbit. When I was a frustrated learning theorist, I did not understand why people were not using learning reductions to solve problems. I’ve been slowly discovering why with VW, and addressing the issues. One of the issues is that machine learning itself was not automatic enough, while another is that creating a very low overhead process for doing learning reductions is vitally important. These have been addressed well enough that we are starting to see compelling results. Various changes:

  • The internal learning reduction interface has been substantially improved. It’s now pretty easy to write new learning reduction. binary.cc provides a good example. This is a very simple reduction which just binarizes the prediction. More improvements are coming, but this is good enough that other people have started contributing reductions.
  • Zhen Qin had a very productive internship with Vaclav Petricek at eharmony resulting in several systemic modifications and some new reductions, including:
    1. A direct hash inversion implementation for use in debugging.
    2. A holdout system which takes over for progressive validation when multiple passes over data are used. This keeps the printouts ‘honest’.
    3. An online bootstrap mechanism system which efficiently provides some understanding of prediction variations and which can sometimes effectively trade computational time for increased accuracy via ensembling. This will be discussed at the biglearn workshop at NIPS.
    4. A top-k reduction which chooses the top-k of any set of base instances.
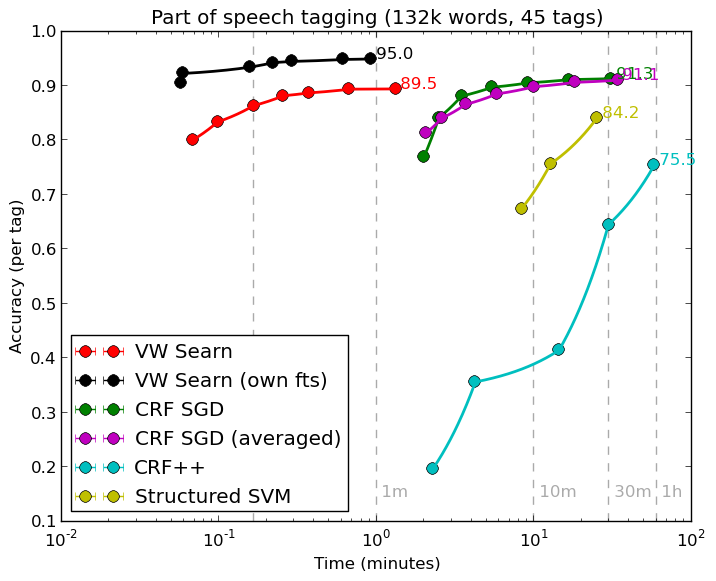
  • Hal Daume has a new implementation of Searn (and Dagger, the codes are unified) which makes structured prediction solutions far more natural. He has optimized this quite thoroughly (exercising the reduction stack in the process), resulting in this pretty graph.
    part of speech tagging time accuracy tradeoffs
    Here, CRF++ is commonly used conditional random field code, SVMstruct is an SVM-style approach to classification, and CRF SGD is an online learning CRF approach. All of these methods use the same features. Fully optimized code is typically rough, but this one is less than 100 lines.

I’m trying to put together a tutorial on these things at NIPS during the workshop break on the 9th and will add details as that resolves for those interested enough to skip out on skiing 🙂

Edit: The VW tutorial will take place during the break at the big learning workshop from 1:30pm – 3pm at Harveys Emerald Bay B.

Ben Taskar is gone

I was not as personally close to Ben as Sam, but the level of tragedy is similar and I can’t help but be greatly saddened by the loss.

Various news stories have coverage, but the synopsis is that he had a heart attack on Sunday and is survived by his wife Anat and daughter Aviv. There is discussion of creating a memorial fund for them, which I hope comes to fruition, and plan to contribute to.

I will remember Ben as someone who thought carefully and comprehensively about new ways to do things, then fought hard and successfully for what he believed in. It is an ideal we strive for, that Ben accomplished.

Edit: donations go here, and more information is here.